
Both. Not either/or. A cheap heartbeat service (UptimeRobot-class) watches money sites every few minutes. Agents run the deep daily sweep, cloak checks, registry hygiene, and triage. If you put every parked domain on a 1-minute SaaS check, or ask a model to be the ping loop, you burn money and train people to ignore alerts.
This page is the operating model Local Service Spotlight uses for the website fleet. Anyone standing up fleet management can copy the lanes. The runnable probe recipe lives on the parent skill: Fleet Uptime Monitor. The BlitzMetrics fleet-uptime-monitor page stays an SEO leaf. This article is the control plane: who does what, what overlaps, and what does not.
GCT (Goals, Content, Targeting)
- Goal: Publish one definitive public how-we page that answers “UptimeRobot or agents?” with the layered operating model, so ops and clients can trust green and copy the lanes.
- Content: Verified registry facts (354 rows; monitoring_status breakdown), July 2026 outage lessons, skill hard rules, Data 7am PT consume + flake gate, and the honest UptimeRobot sync gap.
- Targeting: Fleet operators, web function owners, and agency teams who manage dozens to hundreds of sites and need an honest uptime control plane.
The short answer
| Question | Answer |
|---|---|
| UptimeRobot or agents? | Both, different jobs — heartbeat SaaS + Codex deep sweep + Data consume |
| Overlap? | Only if you run two full-fleet AI probes or put every domain on paid minute-checks |
| Who owns the list? | GitHub fleet registry (sheets are views) |
| Who pings all night? | Heartbeat SaaS on the ENABLED money cohort + 3 anchors |
| Who diagnoses cloak / 5xx layer / fleet-wide? | Fleet Uptime Monitor (Codex scheduled sweep) |
| Who consumes receipts and decides chat vs quiet? | Data desk (7:00 AM PT), with a flake gate |
| Who sends P1 email? | Drafted to web@blitzmetrics.com — agents draft, humans send unless a separate send seat is approved |
| Auto-sync registry → UptimeRobot? | No (as of 2026-09-09). Registry has monitoring_status; agent-runtime has no automated sync |
Why one tool is not enough
July 21, 2026: ~150 client sites returned HTTP 500 with a fully rendered HTML body. A monitor that only asked “did a body come back?” would have stayed green. Status code and layer probes matter.
July 27, 2026: the credential cache was 111 days stale. Probes passed 18/18 while 18 live client sites were never on the list. Green is worthless if the roster is frozen.
May 2026 (BlitzMetrics alone): Search Console 5xx alerts arrived after the fact. A short-interval heartbeat on the money site closes that detection gap. Case study: How we set up uptime monitoring for BlitzMetrics.
September 2026 pattern: Codex ATTENTION on ENABLED sites often shows human Errno 51 / TimeoutError while Googlebot still gets 200, and an independent box check returns 200/200. That is transport flake, not an outage. Without a flake gate, chat and P1 email cry wolf.
Heartbeat SaaS does not see cloakers, soft-404 catch-alls, or “PHP dead but robots.txt still 200.” Agents do not replace a 5-minute ping on localservicespotlight.com.
Layer map (copy this)
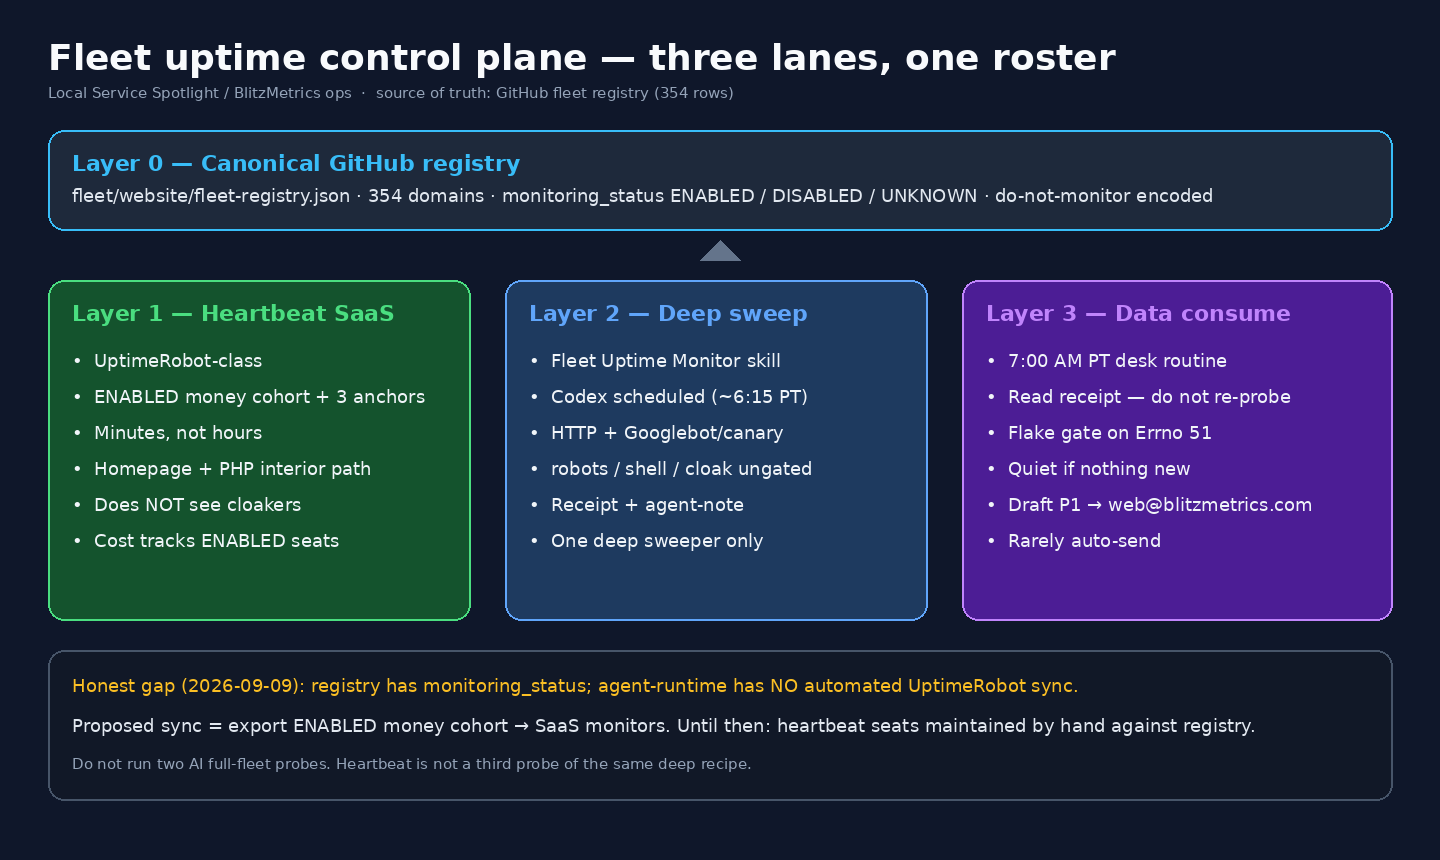
GitHub fleet registry  (source of truth)
        |
        +---> Heartbeat SaaS (UptimeRobot-class)
        |       ENABLED money sites + 3 anchors
        |       minutes, email/SMS/webhook
        |
        +---> Codex / Fleet Uptime Monitor skill
        |       ~6:15 PT daily (or scheduled deep run)
        |       HTTP + Googlebot/canary + robots/shell
        |       receipt + agent-note in agent-runtime
        |
        +---> Data desk (consume only)
                7:00 AM PT routine
                flake gate on named Errno-51 / timeout rows
                quiet if nothing new; ATTENTION/P1 when real
Do not add a second AI full-fleet probe on Grok, Claude, or another seat. One deep sweeper. One consume desk. Heartbeat is not a third probe of the same recipe.
Layer 0 — Canonical roster (GitHub)
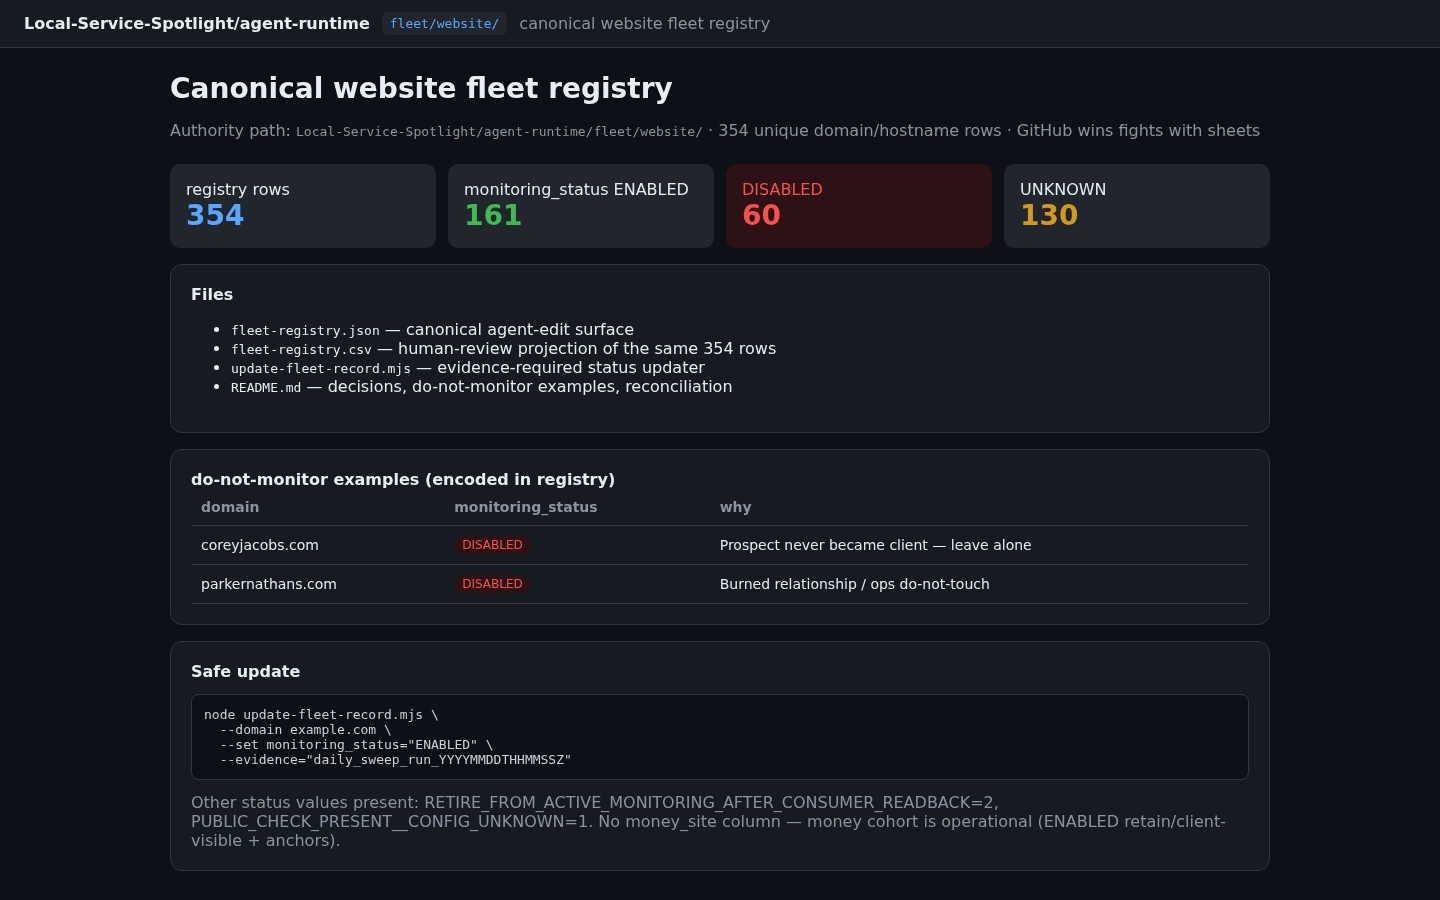
Authority: Local-Service-Spotlight/agent-runtime under fleet/website/ (fleet-registry.json / CSV + README). Updates go through update-fleet-record.mjs with evidence. Google Sheets and BlitzAdmin caches are human views or caches. They do not win fights with GitHub.
Verified counts (fleet-registry.csv)
| Field | Count |
|---|---|
| Total unique domain/hostname rows | 354 |
monitoring_status=ENABLED | 161 |
monitoring_status=DISABLED | 60 |
monitoring_status=UNKNOWN | 130 |
RETIRE_FROM_ACTIVE_MONITORING_AFTER_CONSUMER_READBACK | 2 |
PUBLIC_CHECK_PRESENT__CONFIG_UNKNOWN | 1 |
There is no money_site column in the registry. “Money sites” for the uptime lane are an operational cohort: ENABLED / retain / client-visible domains plus the three anchors — not a CSV flag.
What “money sites” means vs SEO “money pages”
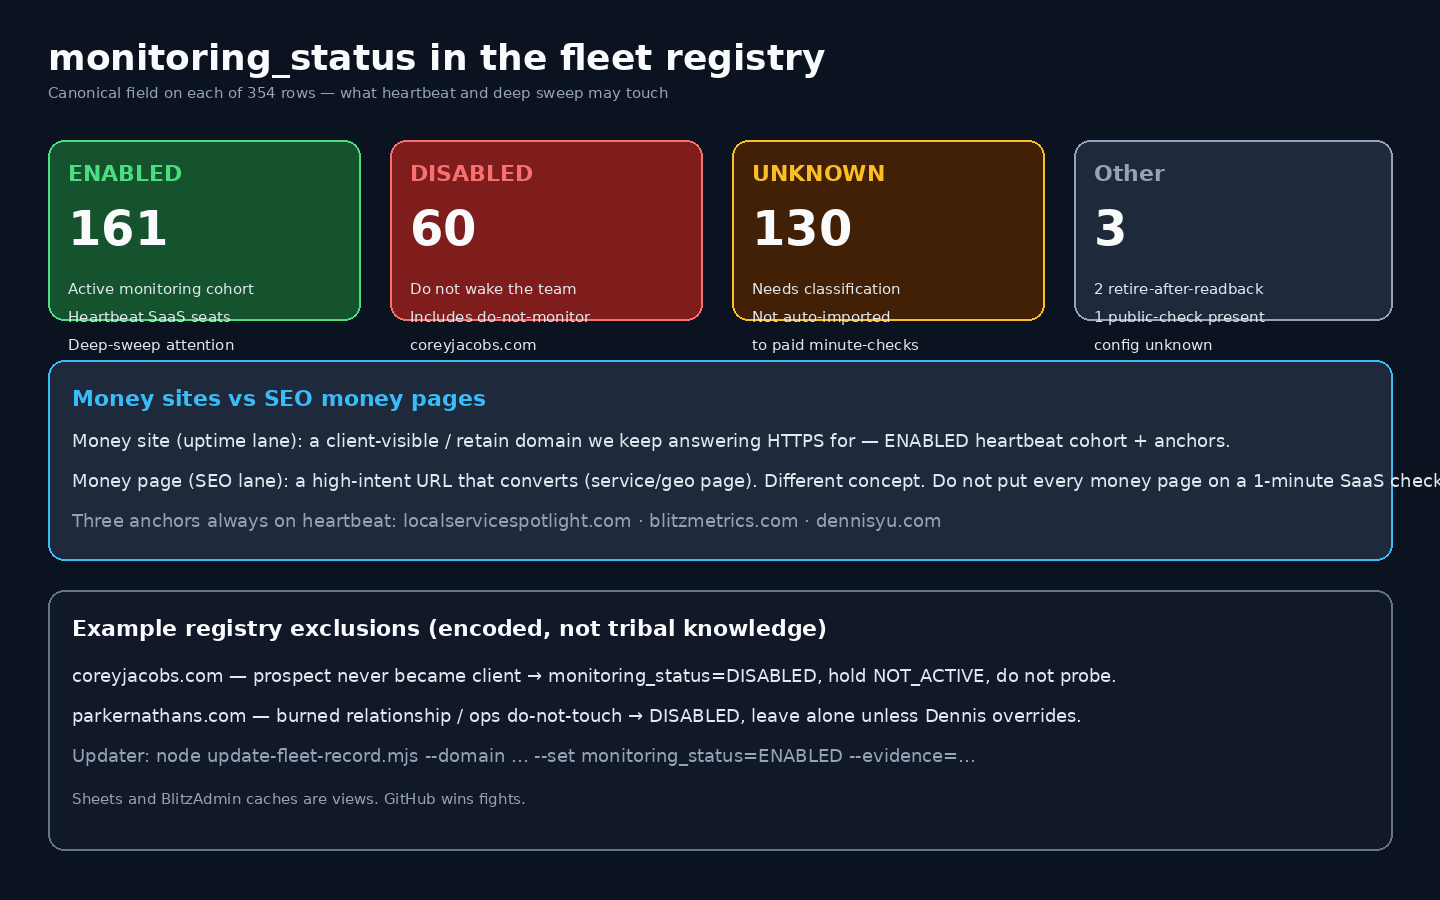
- Money site (uptime lane): a domain the business still needs answering HTTPS — client-visible or retain. These are the seats that belong on short-interval heartbeat checks (the ENABLED money cohort) plus anchors.
- Money page (SEO lane): a high-intent URL on a site that converts (service page, geo page, offer page). That is a content/SEO concept from the money tree. Putting every money *page* on a 1-minute SaaS monitor is the wrong unit and burns the bill.
Do-not-monitor (encoded, not tribal knowledge)
Mark exclusions in the registry, not in someone’s head:
- coreyjacobs.com — prospect who never became a client →
monitoring_status=DISABLED, leave alone unless Dennis Yu explicitly overrides. - parkernathans.com — burned relationship / ops do-not-touch →
DISABLED, do not probe or give daily attention.
Also exclude RETIRED, Not Active, and other DISABLED backlog from ATTENTION noise unless status changed. Hub: Web Function.
Rules that keep green trustworthy:
- Union more than one roster when building a probe set (credential cache + publishing targets historically; registry is now canonical).
- Report roster age on every healthy close-out. A roster that stopped updating is the incident.
- Never silently fall back when a roster is missing.
- Mark exclusions in the registry with evidence via
update-fleet-record.mjs.
Layer 1 — Heartbeat (UptimeRobot-class)
Job: tell a human within minutes that a money site stopped answering HTTPS.
Scope: ENABLED / retain / client-visible money sites plus the three anchors: localservicespotlight.com, blitzmetrics.com, dennisyu.com. Do not put every parked, deferred, UNKNOWN, or do-not-monitor domain on a 1-minute plan.
Config pattern (from the May BlitzMetrics setup, scaled):
- HTTPS check on homepage and one interior path that needs live PHP (CDN-cached home can lie).
- Interval: short (minutes), not hours.
- Alert channel:
web@blitzmetrics.comor the ops channel that actually wakes someone. - Prefer “confirmed down” (2–3 fails) on the wide fleet to cut noise; keep aggressive alerting on the three anchors if you want.
What it does not do: cloak detection, robots shape, shell markers, shared-IP blast-radius diagnosis, registry writes, flake classification vs Googlebot.
Cost control: SaaS seat count tracks ENABLED money sites (~161 ceiling on status alone; operational money cohort is the retain/client-visible subset), not the full 354 inventory and not the 130 UNKNOWN rows.
Honest gap — no automated UptimeRobot sync
As of 2026-09-09, code search in Local-Service-Spotlight/agent-runtime for UptimeRobot sync / export-ENABLED / createMonitor returned 0 implementation hits. Mentions of UptimeRobot exist in outage notes and unrelated site-health modules; they are not a registry→SaaS sync.
Proposed sync (not built): export monitoring_status=ENABLED money cohort (+ anchors) → create/update SaaS monitors; remove monitors that flipped DISABLED / do-not-monitor. Until that ships, heartbeat seats are maintained by hand against the GitHub registry.
Layer 2 — Deep sweep (Fleet Uptime Monitor)
Job: catch what a status ping cannot: fleet-wide 5xx, cloaking, reinfection, parked/stub, soft-404 catch-alls, layer diagnosis.
Owner: scheduled Codex / Cowork job running the Fleet Uptime Monitor skill. Cadence has moved from every 3h toward a daily deep run ahead of the morning agent wave. Canary pass (3/3) gates trust in the receipt.
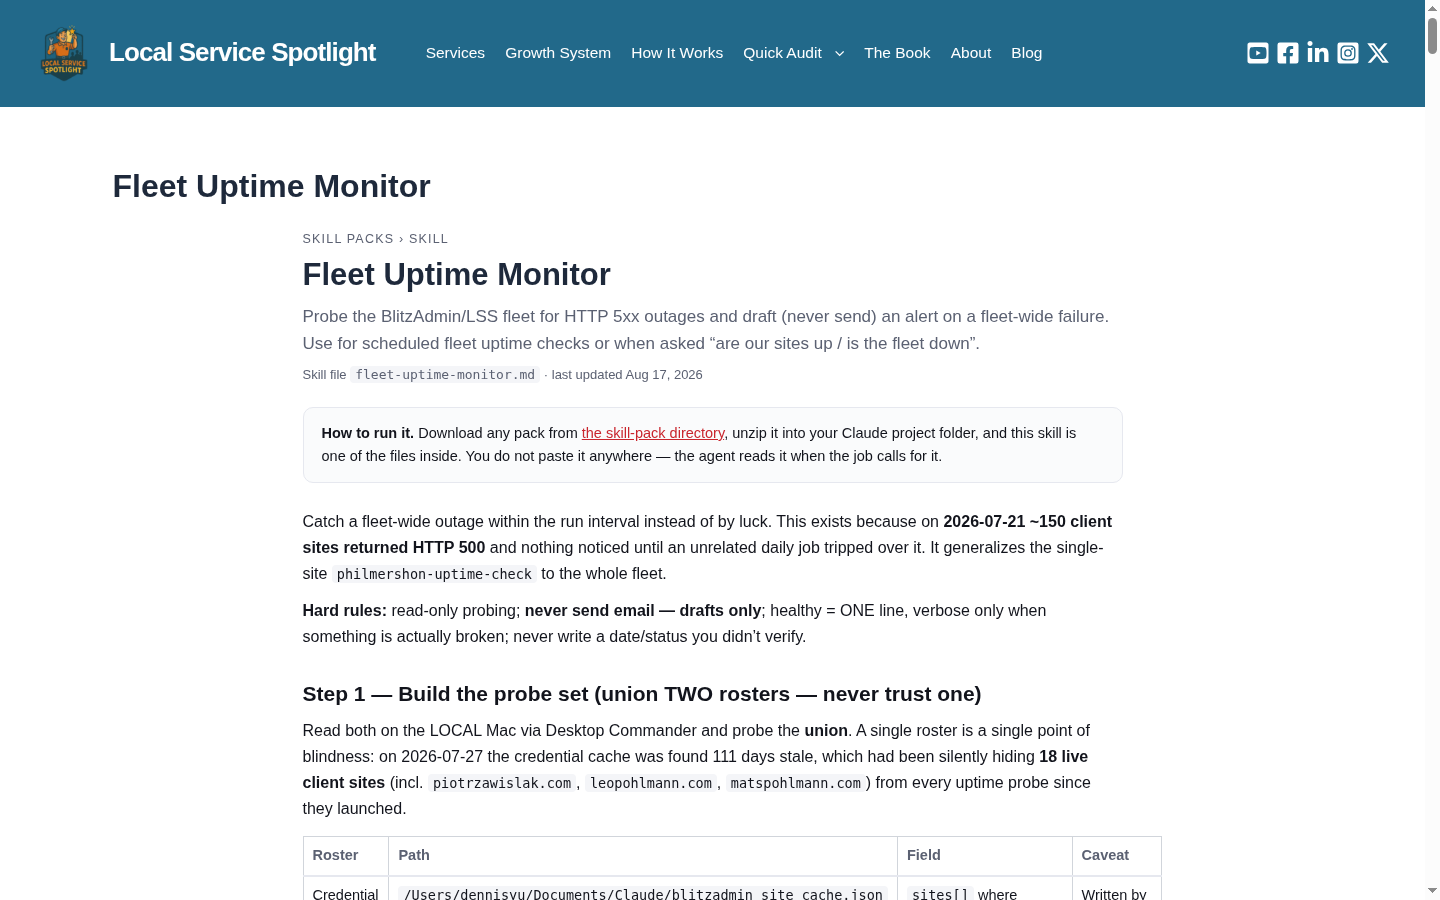
Hard rules from the skill (do not weaken):
- Read-only probes. Draft alerts; do not auto-send unless a separate send seat is approved.
- Healthy = one line. Verbose only when something is broken.
- Status code is the signal; body-present is not.
- Cloak / canary / robots / shell checks are ungated (not only on already-down sites). A check that only runs on broken sites cannot catch a cloaker that returns 200.
- Deep-probe non-healthy sites with controls (
/wp-cron.php, nonexistent URL expects 404, static asset, dig for shared IP). - Force-verify known reinfection cohort every run until a human removes them.
- Incident files get a UTC time in the filename so same-day runs do not overwrite each other.
- Exactly one fleet-uptime draft per day when escalating.
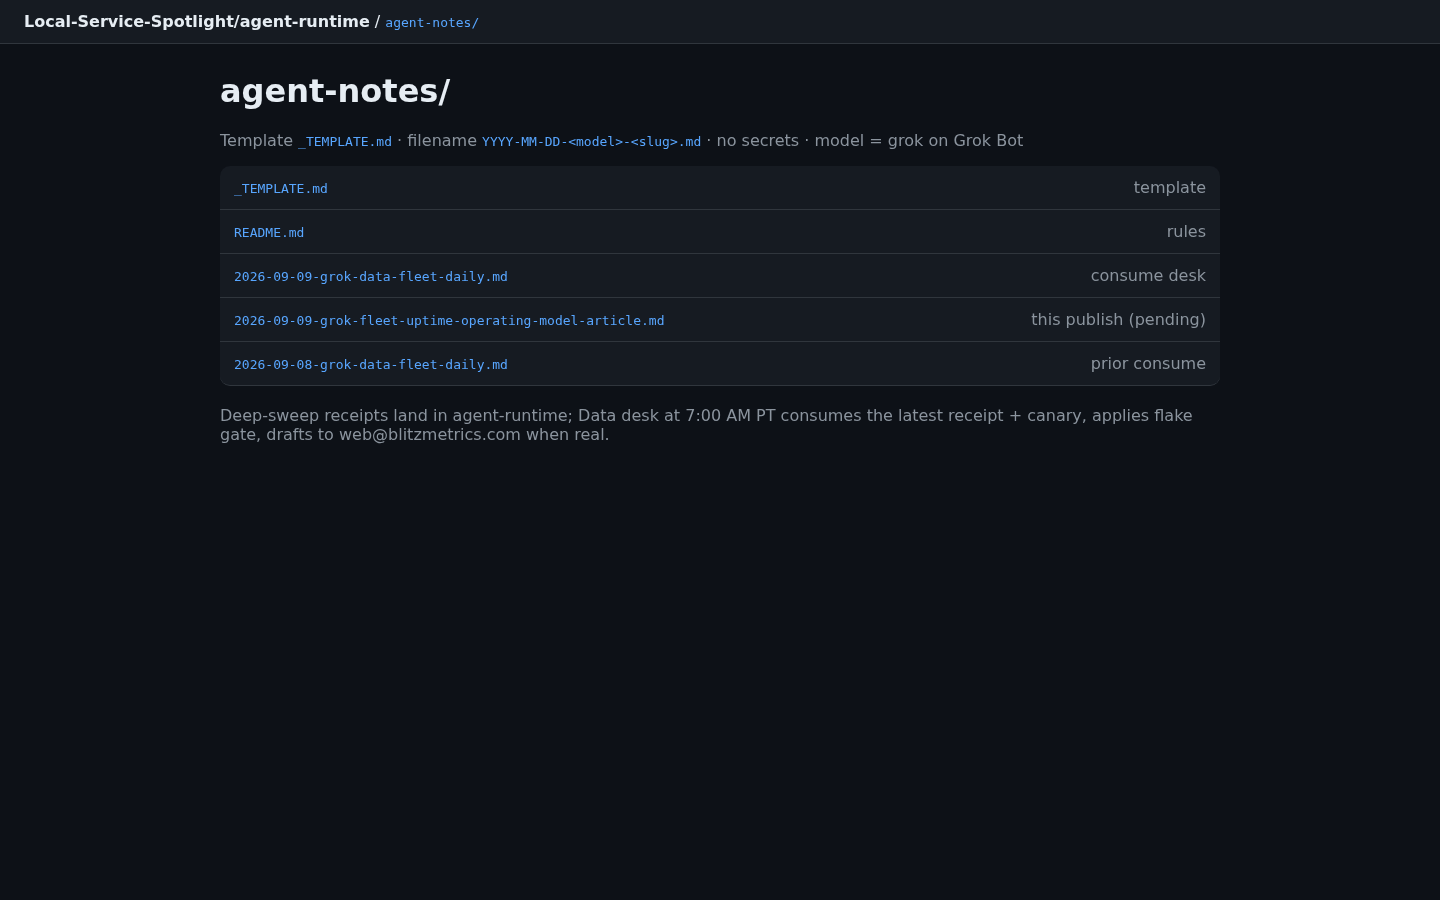
Receipts and agent-notes land in Local-Service-Spotlight/agent-runtime. Marketplace security-audit remains the canonical verdict owner for infection-class findings; this monitor feeds it, it does not invent a second marketplace skill.
Probe internals and field lessons continue on the skill page and the BlitzMetrics definitive leaf.
Layer 3 — Consume desk (Data)
Job: read today’s Codex receipt + registry, independent-check anchors, apply the flake gate, decide quiet vs chat vs P1 draft.
Schedule: 7:00 AM America/Los_Angeles (CRON_TZ=America/Los_Angeles 0 7 * * *).
Does:
- Consume the latest full receipt and canary. Does not run a second full-fleet probe.
- Skip do-not-monitor and known DISABLED backlog noise unless status changed.
- Independently HTTPS-check the three anchors (human + Googlebot when diagnosing).
- Flake gate (2026-09-09): before chat ATTENTION on Errno 51 / TimeoutError / human-ERR+Googlebot-200, re-check only the named domains from this desk. If independent check is 200/200, record agent-note only — no chat ATTENTION, no P1.
- Critical durable outages / INFECTED / cloak → draft to
web@blitzmetrics.com. Route host/DNS work to IT (Austin). Registrar sessions stay with the owner of that registrar seat — not a paste-keys loop through Dennis.
Does not need Amazon keys. Public HTTPS and GitHub receipts are enough for the uptime lane. Host fixes use the shared AWS seat IT already runs.
Alert routing
| Finding | Owner | Action |
|---|---|---|
| Anchor or money site down on heartbeat | Ops / web@ | Investigate now |
| 1 site 5xx on deep sweep | Web / IT | Single-site draft + watchlist |
| ≥3 sites 5xx or shared-IP cohort down while control anchor 200 | Web | Fleet-wide outage playbook; expand sample |
| Cloak / canary fail / infection markers | Security + web | P1; outranks uptime; do not “clean” over REST |
| SUSPECT off-fleet A / wrong NS | IT + registrar owner | DNS cutover with evidence; registry update |
| Errno 51 that clears on independent 200/200 | Data | Agent-note only |
| Stale roster (>30d) | Whoever owns roster refresh | Roster itself is the incident |
Agents draft; they rarely auto-send. One draft inbox (web@blitzmetrics.com). Never train the team with three contradictory drafts per day.
What counts as overlap (avoid these)
| Bad pattern | Why it hurts |
|---|---|
| Two AI full-fleet probes (Codex + Grok both sweeping 200+ sites) | Double cost, conflicting receipts, nobody trusts either |
| UptimeRobot on every parked / do-not-monitor / UNKNOWN domain | Alert fatigue + bill |
| Agent as the only 24/7 ping | Models are expensive and slow for “is HTTPS up?” |
| Heartbeat alone | Misses cloakers and “200 that is spam” |
| Sheet as source of truth | Stale rows hide sites; GitHub wins |
| Clearing cloak on uptime alone | July 29 pattern: 200 with injector still live |
| Chat ATTENTION on every Errno 51 without flake gate | Team ignores the channel |
| Inventing a registry→UptimeRobot sync that does not exist | False confidence; seats drift from ENABLED |
How to stand this up on another fleet (verification checklist)
- Inventory domains into a versioned registry (GitHub JSON/CSV). Mark ENABLED, DISABLED, RETIRED, do-not-monitor with evidence.
- Pick three anchors on different failure domains (different IPs if you can).
- Heartbeat SaaS: import only ENABLED money sites + anchors. Homepage + one PHP interior page. Confirmed-down on wide fleet.
- Install the Fleet Uptime Monitor skill (or equivalent) on one scheduled AI seat. Wire canary + receipt folder.
- Assign one consume desk (person or agent) that reads receipts and never re-probes the whole fleet.
- Write the flake gate into that desk’s standing orders (independent re-check named Errno-51 / timeout rows before chat/P1).
- Alert path: one draft inbox (
web@…). Humans send unless a send seat is approved. - Publish the skill page + this operating model. Link both from your web-function hub. Link UP to the skill; keep vendor brand pages as SEO leaves only.
- Agent-note after every substantive run. No secrets in notes.
- Verify: registry row count matches reality; ENABLED seats ≈ heartbeat monitors; deep receipt exists before 7am PT consume; independent anchor checks 200/200 on a healthy morning; no second AI full-fleet probe scheduled.
Pass / fail checks
| Check | Pass |
|---|---|
| Registry authority | GitHub fleet/website/ wins vs sheet |
| Heartbeat scope | ENABLED money + 3 anchors only |
| Deep sweeper count | Exactly one scheduled AI seat |
| Consume desk | Reads receipt; does not re-sweep fleet |
| Flake gate | Errno 51 → independent 200/200 → note only |
| Alert drafts | Land at web@; no surprise auto-send |
| Sync honesty | Document whether SaaS is auto-synced (today: no) |
Two doors (how-we)
- We can run this for you: talk to the Local Service Spotlight web function / ops team about fleet monitoring as part of website operations.
- DIY: install the Fleet Uptime Monitor skill, copy the registry pattern under
fleet/website/, and follow the checklist above. Skill packs: skill packs.
Related reading
- Fleet Uptime Monitor skill page (parent)
- Fleet Uptime Monitor (BlitzMetrics SEO leaf)
- How we set up uptime monitoring (single-site heartbeat case)
- Web Function
- Article guidelines
- Scheduled jobs fleet
- The Fleet Audit (authority signals; not a substitute for uptime)
FAQ
Should we cancel UptimeRobot now that agents run?
No. Canceling the heartbeat puts detection back on a once-a-day model run and on Google finding 5xx first.
Should Data ping every site every morning?
No. That duplicates Codex and fights the “one deep sweeper” rule. Data consumes and flake-gates.
Can we use Pingdom / Better Stack / Checkly instead of UptimeRobot?
Yes. The brand does not matter. The lane does: short-interval HTTPS on the money cohort, separate from the deep AI sweep.
Is the Projection Google Sheet the monitor?
No. It is a human board. GitHub registry + receipts are authoritative.
What about sites we do not renew or burned relationships?
Registry do-not-monitor / DISABLED. Keep them off heartbeat and out of ATTENTION noise. Document why in the registry evidence, not in chat lore.
Does the registry auto-create UptimeRobot monitors?
No. Today monitoring_status is the signal humans (and future sync code) should follow. Do not invent a sync that is not in agent-runtime.
Operating model as of 2026-09-09. Probe internals and field lessons continue to live in the Fleet Uptime Monitor skill file; update this page when lanes change, not when a detector gains a new residual bucket. Writing follows article guidelines.
Originally published .